NetraOCR extracts clean JSON from invoices, contracts, IDs, medical records — anything scanned, typed, or handwritten — in around 6 seconds. With tamper detection built in, so you catch altered documents before they enter your system.
Printed, scanned, or handwritten — layout-aware extraction understands tables, columns, and nested fields across any document type, not just raw text.
6s
Average response time
Typical documents return structured JSON in around six seconds.
200+
Documents per batch
Queue large uploads once, pick results up asynchronously via webhook or API.
AES-256
Encryption at rest
TLS 1.3 in transit, AES-256 at rest, zero plaintext storage. Security First.
Language translation
Any input language. Your preferred output.
Upload documents in any language and get the extracted results in the language you choose. NetraOCR handles the translation, so your team can work with the output it needs.
The Tour
Explore the NetraOCR workspace
From uploading files to agent-powered categorisation and structured results, explore the tools that handle your document workflow.
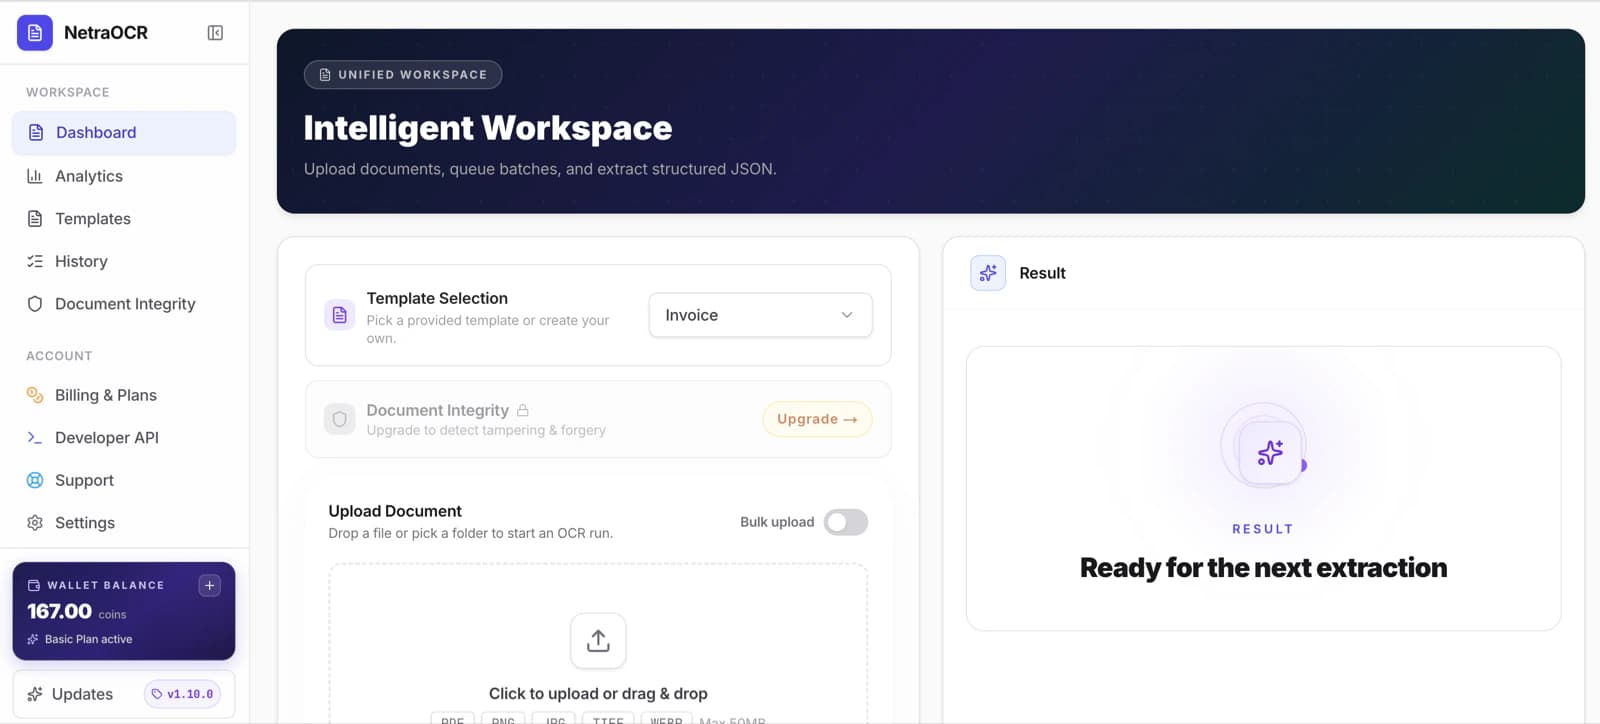
01 — Unified Control Center
Intelligent Dashboard
Upload documents and orchestrate extraction queues seamlessly.
A centralized operational hub engineered for speed and volume. Track processing pipelines, monitor dynamic item queues, and review extracted document states in real time.
Multi-format support for PDFs, scanned images, and invoices
Batch queues up to 200 documents with async processing
Instant search, filtering, and single-click CSV/JSON exports
02 — Extraction Schema Library
Template Studio
Define custom parsing blueprints for any document structure.
Remove brittle hard-coded extraction parameters. Create structured templates using our visual builder, define target JSON schemas, or let the AI model auto-detect and generate layouts.
Visual field builder with description-based prompting
AI template generation from simple document uploads
Just drop in your files. Let the agent do the rest.
Skip the hassle of sorting documents by hand. Upload a mixed batch and let the agent categorise each file, match it to the right template, and extract clean, structured results ready for your workflow.
Automatic categorisation for mixed document batches
The right extraction template for each document
Integrity checks and connector delivery when enabled
04 — Forensic Document Auditing
Tamper & Fraud Settings
Deploy pixel-level and cryptographic anomaly flags automatically.
Protect your operations from financial fraud and forgery. Check every scan and PDF for altered numbers, modified text blocks, metadata mismatches, and copy-paste traces in around six seconds.
Advanced forensic level tamper detection and heatmaps
Active risk score profiles tailored per workspace
Immutable cryptographic audit logs ready for compliance
05 — Real-Time Operational Insights
Advanced Analytics
Monitor your document pipelines, balance logs, and efficiency metrics.
Comprehensive financial and efficiency reporting. Auditable visualizations show coin consumption patterns, accuracy averages, extraction velocities, and plan-level discount benefits.
Dynamic charts showing monthly volume and cost averages
Success rate tracking and workflow speed diagnostics
06 — Document Audit Trail
Job History
Track, review, and filter all processed documents and extraction runs.
A complete searchable archive of your workspace activity. Inspect individual extraction results, download verified JSON models, review integrity score history, and track status pipelines.
Search and filter by document name, status, or date range
Single-click detail view to compare raw documents with JSON side-by-side
Comprehensive status tracking from processing to delivery success
netraocr.shivicx.com/dashboard
Intelligent Dashboard01 / 06
Connectors
Bring NetraOCR directly to your workflows.
Connect Slack, WhatsApp, Tally, Zoho Books, and Google Drive. Import documents, let the agent handle categorisation and extraction, and sync results to the tools you already use. Less manual work. A simpler workday.
Slack: Processing updates and document integrity alerts.
WhatsApp: Import documents shared in chats.
Tally: Sync extracted invoices and bills.
Zoho Books: Sync invoices, bills, expenses, and orders.
Google Drive: Import documents from cloud storage.
Built for the documents you work with
Works with every document type.
Different layouts. Different formats. One way to get usable data. Turn printed, scanned, or handwritten documents into structured fields your team can put to work.
01
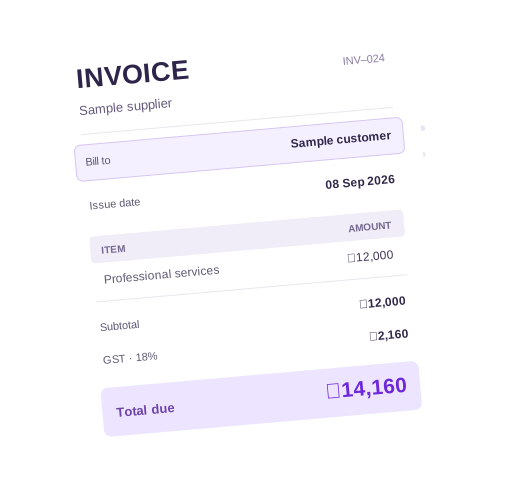
Invoices & purchasing
From purchase to payment, in one format.
Illustrative sample
What you can extract
Invoices, receipts & purchase orders
Bring supplier documents into a consistent format for accounting, reconciliation, and purchasing.
Vendor details
Line items
Tax breakdown
Totals
02
Bank statements
Every transaction, ready to reconcile.
What you can extract
Bank statements
Turn statement tables into structured transactions you can search, compare, and reconcile.
Account details
Transaction dates
Credits & debits
Balances
03
Identity & KYC
Bring the details into focus.
What you can extract
ID cards & KYC documents
Extract identity fields from cards and onboarding records for your verification workflow.
Names
Document numbers
Dates of birth
Addresses
04
Contracts & leases
Find the terms that matter.
What you can extract
Contracts & lease agreements
Find the parties, dates, and terms you need across long documents, using your own extraction template.
Parties
Effective dates
Payment terms
Key clauses
05
Tax & payroll
Turn recurring paperwork into usable data.
What you can extract
Tax forms & payslips
Capture reporting periods, earnings, and deductions without retyping recurring forms.
Tax identifiers
Reporting periods
Earnings
Deductions
06
Bills & records
Everyday documents. Organised information.
What you can extract
Utility bills & medical records
Collect the details that matter from everyday bills and reports, with fields tailored to each document.
Names & dates
Reference numbers
Amounts
Report values
Scroll to explore document types01 / 06
PDFs, scans & photosWork with the files you already have.
Printed or handwrittenCapture fields across different layouts.
Your fields, your templateDefine what to extract for other document types.
The hidden cost
Manual document work is quietly killing your ops
Every forged invoice, every retyped total, every day added to month-close — these costs hide in plain sight until someone adds them up.
14 minper document
Industry average time a clerk spends extracting data from a single scanned document. Across 500 docs a month, that's one full-time hire doing copy-paste.
1 in 60documents is tampered
Subtle edits to numbers, dates, names, and signatures slip past human review. By the time it's noticed, the decision or payment has already cleared.
80%of manual entries need rework
Typos, missed fields, and wrong values from manual data entry cause downstream rework — quietly inflating costs across finance, KYC, claims, and ops.
Built for
Teams that can't afford errors
Finance & AP
Close your books 3 days faster.
Auto-extract vendor, totals, GST breakdown, and line items from every invoice. Catch forged documents before they hit payroll.
Vendor + GSTIN matching
Line-item extraction
Tamper flag before payout
KYC & Compliance
Verify 10,000 IDs a day. With proof.
Parse KYC docs, tax forms, and ID cards into structured fields. Every decision is logged with integrity scores — ready for regulators.
ID number + DOB parsing
Edit-detection on scans
Immutable audit trail
Operations
Stop hiring clerks to retype PDFs.
Route contracts, POs, and lease agreements to the right system automatically. Your team reviews edge cases — not every document.
Custom field schemas
Webhook delivery
Batch async queue
Compliance and Trust
Corporate Trust & Security
Independently certified, annually audited, and recognized by national innovation programmes.